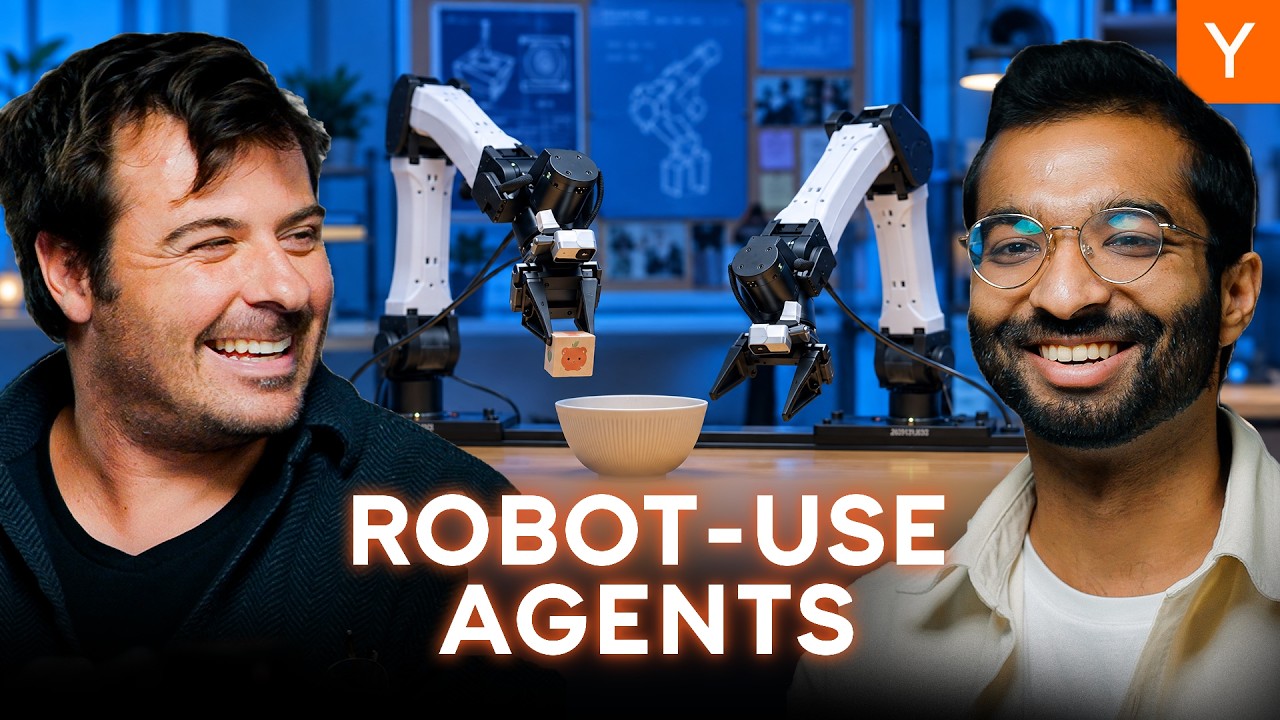
Robotics has spent years trying to collect enough robot data to train robot models. The founders of Waddle Labs and RoboCurve are betting that the fastest route runs through code instead: a single frontier language model that writes policies, calls tools and adapts to new hardware with little or no robot-specific training.
MIT professor Phillip Isola gave the idea a name in an essay that circulated widely: robot-use agents, general-purpose models that make many different robots more capable. Demos from both startups were cited in it. The clips showed language models unscrewing caps, uncapping a pen and coordinating several robots at once.
Waddle Labs builds a harness that lets LLMs control robots effectively, collects the resulting data, and uses it to train better LLMs. RoboCurve is an evaluation company for physical AI that tests any robot with any model, whether that's an LLM, a vision-language-action model or a world action model, across hands, grippers, arms, humanoids and quadrupeds. One builds the controller; the other measures it. Both converge on the same claim.
The timing matters because coding agents have quietly become the most general capability in AI. Nobody at the frontier labs set out to build robot controllers when they poured compute into coding. The robotics payoff looks like a side effect, and if it holds, it changes where robotics companies should spend their money.
The data bottleneck held robotics back more than the architecture did
The lineage starts with RT-2, which took a language model pretrained on web text and images and fine-tuned it to output end effector poses (coordinates that translate into joint commands) in place of English. Jay, co-founder of RoboCurve, credits its strength to that pretraining: the web data made the VLA better than a robotics foundation model trained from scratch.
The Waddle Labs team pushes the point further. VLAs are built on language models too. They could reason and write code in principle. So the lesson isn't which architecture you choose; it's which data you feed it. The field has spent years chipping away at the VLA data bottleneck with slow progress.
"How do you take something that's traditionally out of distribution like robotics and make it something that's in distribution?"
Their answer is to pick a modality where data is plentiful and models already excel, and use it to unlock other domains. If you want coding data and computer-use data inside your robot model anyway, you end up with a general-purpose LLM agent. At that point, they ask, why not start from the best foundation model available?
Code gives a model room to think before it moves
Francois, one of the hosts, maps the shift onto the chain-of-thought moment in math benchmarks. Early models answering GSM8K had to emit the answer immediately, with no room to compute "8 − 5 = 3" first. RT-2 has the same constraint: it must output an action, with no way to allocate more compute to a harder task. Letting the model reason, or write compact code, before acting removes that ceiling.
The research signal was visible early. Google DeepMind's code-as-policies work, published around late 2022, handed a model a list of Python functions such as "pick up object" or "move to pose" and let it compose them. Jay recalls what surprised researchers most: it worked one-shot. The models needed no extra robot data because they'd already absorbed enough code to know what to do first and second to move a block into a bowl.
Voyager extended this in Minecraft by having the agent write new tools on the fly and invoke them later, compressing experience into reusable code. Francois doubts the labs that bet everything on coding in 2024 foresaw any of this. They wanted to automate the ML engineer. Robot control came along for free.
He also frames the shift through François Chollet's distinction between transduction and program induction. Learning a direct mapping from x to y is slow and data-hungry. Emitting a function that maps x to y, the way a candidate does at a whiteboard interview, is far more sample-efficient. Classic program synthesis stalled because finding the right inductive biases was hard. A frontier model may be what supplies them.
In-context learning adapts cheaply, then saturates
Francois describes an unpublished experiment on how efficiently different learning methods absorb new experience. He held out a task, fed examples into context and measured improvement per sample. Three patterns emerged:
- Improvement was cheap, with no gradient updates and no training FLOPs.
- It was non-monotonic, swinging worse and better quite aggressively.
- It saturated after roughly 20 to 40 examples.
A harder limit sits beyond that. A model trained on a 100,000-token context, he estimates, effectively uses about half, and past that it gets worse. Retrieval helps, like taking an exam with the textbook open. Beyond that sit LoRA at various ranks and then full fine-tuning or RL. His blunt point: if you're Tesla with effectively infinite driving data, learning in context would be absurd. In low-data regimes, it's remarkably strong.
The unsolved problem is the hierarchy between these tiers: when to compress in-context lessons into tools, and when to push them into weights.
A harness turns expensive reasoning into reusable skills
In a live demo, the model the speakers call Astra, which they attribute to OpenAI, watches camera feeds and issues end effector poses turn by turn to drop a block into a bowl. It works. It's also visibly slow.
That's where the harness earns its place. A Waddle Labs founder explains that having the frontier model command every pose is often the wrong tool. Repetitive motions should become code that runs fast without the model in the loop. Tasks it has done before should call a compiled skill that handles edge cases better.
The team calls this domain specialization. A robot deployed in a wet lab to pick up test tubes learns in context, then packages those skills as programs for future agents, a kind of distillation from past experience. The resulting policy graph is mostly deterministic, with deliberate points of variation where a VLM steps in: detecting an object, checking whether a grasp failed, choosing a recovery.
They also see a meta-learning shape here, with a large model programming smaller, faster ones wrapped inside the harness. Papers suggesting that in-context learning approximates gradient descent make the line between weight space and symbolic space, in their words, a little blurry.
On latency, Jay offers a striking number: frontier-class LLM latency improving roughly 2x per month, which would put real-time control within reach by year's end. He presents it as an observed trend without citing a source, and monthly doublings rarely hold for long.
Clicking around Blender teaches a model about physical space
Why would a language model suddenly get good at spatial reasoning? The group leans on Isola's Platonic Representation Hypothesis: models trained on enough data converge toward a shared representation of the world. Jay's concrete version is that a strong enough language model shares its world model with a strong robotics model, so owning one means owning the other.
The Waddle Labs founder points to data. Astra was probably pretrained on far more computer-use and CAD data than earlier models. Dragging a cursor to orbit an object in Blender teaches top and bottom, left and right, the spatial primitives a robot needs. Computer-use data alone wouldn't transfer. Inside a large general model, it does.
Francois spots the irony. Xerox PARC designed the graphical interface to mimic the physical world so humans could use it. Decades later, those GUIs became training grounds that help machines handle the physical world. Harness design can exploit this directly: Jay cites work from Princeton showing that making robot tools resemble computer-use tools, with an agent dragging a cursor to direct the arm, improves physical task performance.
Robotics researchers are arriving from the other side, expanding from teleoperation to egocentric video. Taken to the extreme, you feed coding, computer use and egocentric footage into one model.
The next bottleneck is teaching the system to sleep
Jay reports a consensus among frontier labs and robotics companies that general-purpose robots, able to do what a competent teenager can do with their hands from any natural-language instruction, will arrive within two years. He offers no evidence beyond that consensus, and it's a view held by people with a stake in it.
Waddle Labs sees the path running through consolidation. A frontier model thinking at every step won't be economically useful. Its first pass has to become a faster skill that runs at high throughput.
Francois reaches for biology. Almost every intelligent system sleeps, and during sleep the hippocampus replays the day's memories into longer-term storage. The robotic analogue resembles DAgger-style loops: collect experience, reflect on it, distill it into an updated weight file, possibly for your own smaller model.
DreamCoder did a rigid version of this, refactoring its skill library into compact form during a sleep phase. The open questions now are looser and harder: how to prune a growing library of skills, how to refactor traces, how to manage an expanding store of deployment data.
For anyone building in robotics, the bet has moved. The scarce asset may no longer be robot demonstrations. It may be the harness that decides what a general model should reason through live, what it should compile into code, and what it should sleep on.